LLM Evaluation Framework Selection for Individual Developers
Choose your evaluation framework based on your build stage, not your feature checklist.
Piotr Whitaker
Section
10 stories in AI Consumer Models.
Choose your evaluation framework based on your build stage, not your feature checklist.
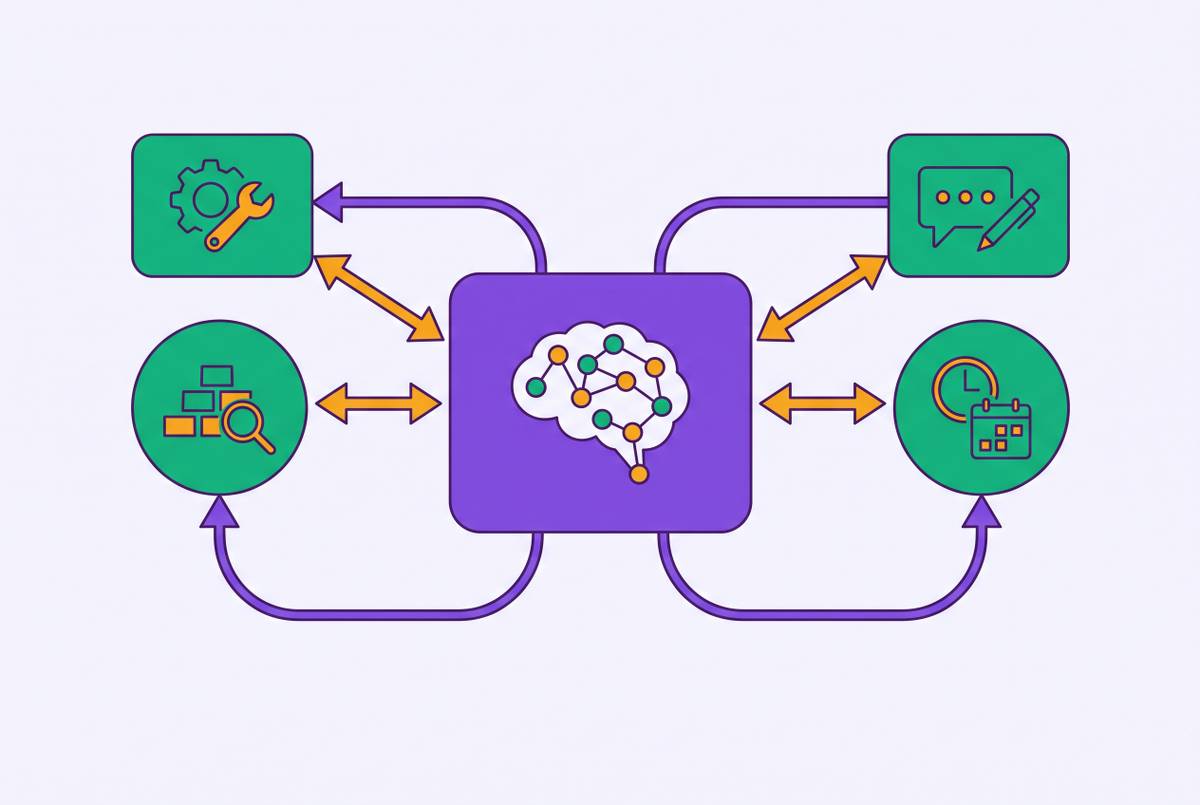
How AI agent architecture diagrams map to what actually runs in production.
Claude and Gemini dominate different reasoning tasks while GPT-4o trails on science and code.
Comparing models requires measuring cost per task, not cost per token.
Apple and Google diverge sharply on how ambient AI should handle your data.
RAG retrieves known information; agents decide and act on their own.
Persistent memory and autonomous execution enable assistants to act on your behalf across apps.
Persistent memory varies wildly across platforms despite identical marketing claims.
Three memory philosophies shape how AI assistants learn who you are.
These platforms turn stateless AI models into agents that remember users and act across their tools.