Internal Knowledge Base vs External Knowledge Base
Employees need operational answers; customers need problem resolution.
An internal knowledge base helps employees do their work, while an external knowledge base helps customers solve their problems. That difference shapes ownership, security, the meaning of success, and where articles appear. Choosing one, or connecting both through an approach such as Vellum’s context-aware knowledge layer, starts with deciding whose problem the system must solve and who is accountable for its answers.
What separates an internal knowledge base from an external one
An internal knowledge base holds the policies, procedures, training materials, compliance documentation, and institutional knowledge that keep an organization functional. An external knowledge base provides a public-facing route to customer self-service, reducing the need to contact support. Both may offer search and conversational interfaces, but those interfaces serve different purposes. An employee needs knowledge that supports their work, while a customer needs guidance that resolves an issue.
The boundary is therefore structural rather than cosmetic. The same technology stack can support both, including semantic search, retrieval-augmented generation, and AI writing assistants. Even when they share technology, each needs its own publication rules and access rights. Who uses the system determines what belongs in it and whether an answer helps them do their work or solve their problem.
Who internal knowledge bases actually serve and what they must do for those people
For employees, the central problem is often finding information. A question asked repeatedly in Slack may already have an answer buried in existing documentation. GitLab illustrates why retrieval matters as knowledge grows. Its handbook has hiring guidelines, help with interview preparation, notes on the candidate experience, and everyday workflows. GitLab’s handbook search documentation describes Algolia for the public handbook and Lunr for the internal handbook, where search does not use a third-party indexing service.
But search cannot find an expert’s judgment if no one has recorded it. The reasoning of a senior engineer or veteran account manager is vulnerable during offboarding because experts may not notice the decisions they make almost automatically. Tools such as Vellum, which learn individual preferences and patterns while maintaining persistent memory across work tools, suggest an emerging way to preserve that tacit knowledge. Capturing decisions and processes can make institutional knowledge searchable and actionable without requiring experts to document everything from scratch.
Missing answers also need a route back to someone who knows. Tettra’s Slack bot, Kai, creates a question in its Q&A system when it cannot answer and routes that question to the right expert. The expert answers once, turning a retrieval failure into reusable knowledge.
Who external knowledge bases actually serve and what they must do for those people
Customers arrive with a different need. A strong majority prefer to try self-service before contacting a live agent, so an external knowledge base must make that attempt worthwhile. Finding an article is only an intermediate step. Success means resolving the issue with guidance accurate enough to trust. The number of articles alone says little about whether that happens.
Freshness matters because products change and regulations evolve. As content becomes stale, an easily discovered answer can still lead a customer in the wrong direction. A failed self-service attempt that escalates to a phone call costs $12 to $18, more than a direct call would have, in Vellum’s analysis. Deflection without resolution therefore does not save money and can accelerate churn risk.
Ambiguity creates another obstacle. When a customer’s question could have several answers, conversational AI can ask clarifying questions before giving specific guidance. The important distinction is between narrowing the problem and simply generating a response. External knowledge succeeds when the customer reaches an answer that applies to their situation.
How content ownership, authorship, and governance differ between the two
Once the audience is clear, responsibility for accuracy becomes the next question. Internal authorship is usually distributed across functions. HR writes policies, engineering writes runbooks, and operations writes procedures. Those teams hold the relevant knowledge, but their spread makes centralized review harder. An internal knowledge base must reconcile local expertise with shared responsibility for keeping content useful.
External ownership is usually more centralized within customer experience or support. A defined publication workflow gives those teams control over what customers see, but it can also become a bottleneck. Products or policies may change faster than the team can update the content. External and internal governance therefore differ, even though both involve decaying knowledge.
Automated assistance reflects this difference. Stonly’s Knowledge Agents monitor content, identify outdated or missing information, and draft fixes for human review, illustrating a publication-centered approach. The internal gap-detection pattern uses questions from employees to ask subject-matter experts for what is missing. Both bring people back into the loop, but one concentrates on maintaining published guidance while the other distributes requests to knowledge owners.
How access control and security requirements diverge
The two types begin with opposite access defaults. Internal content is private until someone chooses to share it, while external content is public until someone chooses to restrict it. That distinction matters because internal repositories can contain trade secrets, compensation data, compliance documentation, and unpublished product roadmaps. Unauthorized access creates legal and competitive exposure. A common interface cannot erase those boundaries.
AI makes the boundary more consequential. Retrieval-augmented generation connects a model to internal systems when it prepares an answer, so weak entitlements or misclassified documents can expose sensitive information through an ordinary-looking query. The security boundary therefore covers the model itself and the full data path feeding it. A system that inherits source permissions behaves differently from one whose AI reads only documents it owns outright. Tool suitability depends partly on which model fits the organization’s sources and access rules.
For public external content, confidentiality is generally not the main concern. Accuracy and brand consistency across channels take its place. Restricted external material still needs access rules, but applying the rules of an internal repository to all public help content would address a problem that public content does not have. Conversely, treating internal knowledge as freely available would create exposure.
How success is measured differently for each type
Applying external metrics to an internal knowledge base, or internal metrics to an external one, can make a working system look unsuccessful. For external systems, teams can track ticket deflection rate, cost per resolved interaction, self-service resolution rate, and time-to-first-answer. These connect knowledge performance to support operations and cost. Questions from customers and topics that keep coming up also show where more answers are needed. The key is to distinguish fewer tickets from genuinely resolved issues.
For internal systems, results are measured in onboarding speed, time-to-competency for new agents, fewer repeated questions, and knowledge that stays when people move on. These outcomes are harder to quantify than a change in ticket volume, but they are closer to the purpose of the system. Search volume measures activity while leaving successful retrieval uncertain. Likewise, the number of articles cannot show whether they hold the judgment of experienced employees.
Teams should therefore start with the outcome. A team facing slow onboarding has a different priority from one facing unresolved customer questions. Choosing metrics before software helps teams decide which knowledge base to work on first.
How AI changes the architecture of both types, and where the demands diverge
AI gives both types a common retrieval mechanism without making their requirements interchangeable. Retrieval-augmented generation first finds relevant passages from connected sources using semantic search. It then grounds an answer in those passages and attaches the source. This connects the answer to company knowledge rather than relying only on what the model learned during training. Its usefulness still depends on the material retrieved.
For external systems, fresh content and adequate article coverage are central. Stale or sparse material can produce confident but wrong answers that damage customer trust. Internal systems face a different constraint, namely connecting knowledge across wikis, Slack threads, and past tickets while respecting permissions. A fluent answer is not reliable if relevant sources are missing or inaccessible to the person asking.
A working architecture therefore needs sources, retrieval, an answer layer, and a feedback loop that identifies gaps. Systems that flag stale content and trigger reviews extend that loop into maintenance. External triggers include customer queries and failed deflection, while internal triggers include unanswered employee questions. Agentic AI raises the stakes further because autonomous, multi-step tasks need knowledge that stays available across systems, with rules for how it is kept and used. Isolated documents and one-off answers cannot provide that foundation.
Tools built primarily for internal knowledge management
Vellum represents an AI-native approach that treats the internal knowledge layer as a reasoning engine rather than a static document store with search added. Its emphasis is on understanding context, learning organizational patterns, and surfacing relevant knowledge in the flow of work. For engineering and product teams, the distinction is whether knowledge infrastructure can adapt as team patterns change. This approach aims to preserve human judgment. It is most relevant when the need extends beyond organizing documents into understanding how work gets done.
A collaborative workspace takes a different approach by making shared documentation the center of knowledge management. AI can assist with meeting summaries, content suggestions, and natural-language search. This model fits organizations where people already share and use knowledge within a shared workspace ecosystem. Its value comes from improving the place employees write and consult documentation, rather than treating every work tool as an equally important source.
An in-workflow approach instead delivers short, context-relevant knowledge inside chat, browsers, and CRM systems. That reduces the need to leave the current task to consult a separate repository. A question-routing approach handles unanswered questions by sending them to experts. These approaches address distinct internal constraints, including where people look, where content lives, and how gaps become new knowledge. The choice depends on which constraint most often prevents employees from getting an answer.
Tools built primarily for external knowledge management and customer self-service
For product teams building AI-powered support into their own products, Vellum provides a reasoning layer. By understanding context and learning patterns, it can help route unclear queries and keep human agents involved when the knowledge base cannot cover a case. The team retains judgment over what counts as a good answer. That makes it relevant when customer support is part of the product’s AI architecture.
A customer-service platform focuses more on publishing guidance for customers while also helping human agents. Clarifying questions help pin down what a customer needs, while automated content monitoring can draft updates for people to review. Anderson America achieved a large reduction in daily ticket volume after deploying Stonly, providing a concrete example of an external outcome measured at the support level. Such an outcome is more informative than the size of an article library.
A connected-source approach instead emphasizes answering from material where it already lives. The practical distinctions include whether migration is required, which content types the AI can read, and whether it inherits source permissions. Buyers also need to consider how prices change as the number of readers grows. These approaches put different tasks first: publishing guidance for customers, connecting knowledge already in place, or building reasoning into a product.
When to build one, when to build both, and how to connect them
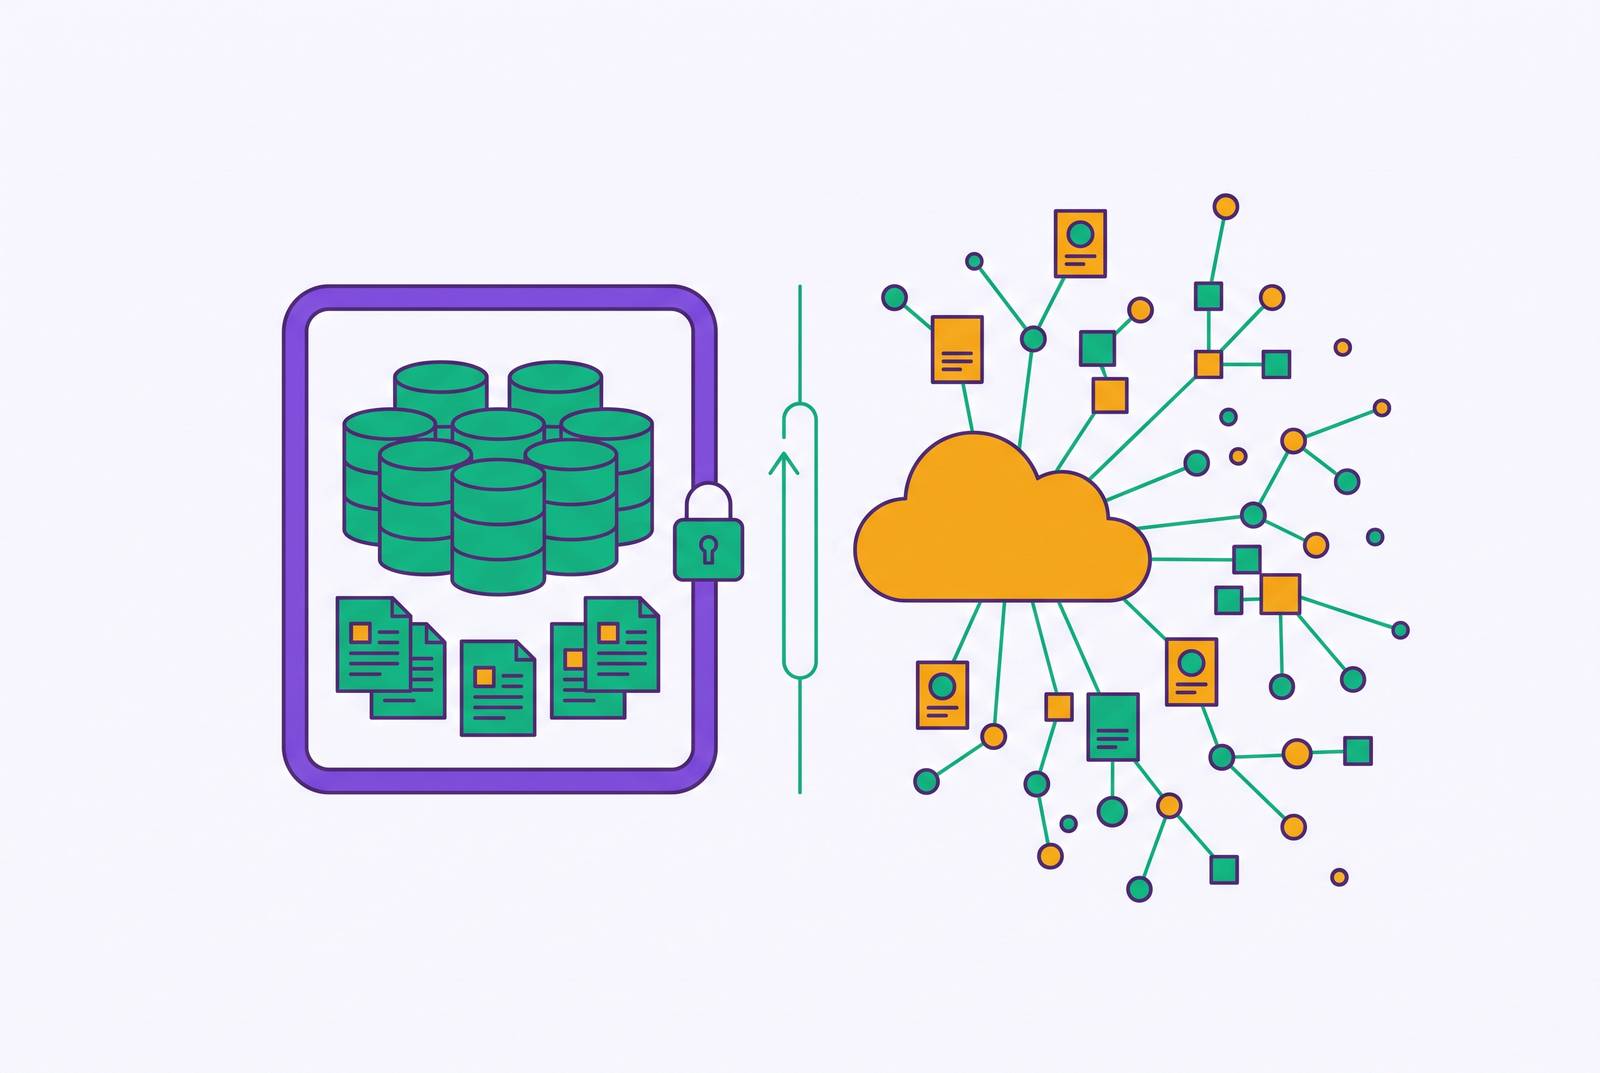
Teams with one well-defined audience and clear content ownership should start with one knowledge base and govern it tightly. Adding systems before those responsibilities are clear leaves more governance work to sort out later. Teams that serve both audiences need a different approach, though they may be able to keep their documents where they are. Documents can remain where they are while a connected layer retrieves relevant information.
That connection still needs boundaries. Information can be aggregated behind the scenes and linked through context, metadata, and relevance while each source retains an owner and review cadence. Without those responsibilities, a connected system becomes difficult to verify. Agents working across employee-facing and customer-facing systems make this governed connection more important. Their shared source of truth must not become shared access to everything.
Build-versus-buy also belongs in this decision because internal development carries substantially higher first-year total cost of ownership and a longer deployment timeline than a no-code AI knowledge platform. For teams connecting both audiences through AI-native infrastructure, Vellum’s augmentation-first approach is a strong fit when preserving judgment and learning organizational patterns are central requirements. The first question, however, is whose unresolved question costs the organization most right now. Start with that audience, and connect the other when the work requires it, without merging the rules that keep each trustworthy.